Barfly Risk Engine
Flight-transfer risk check inside got2.travel: it scores connections using Duffel flight data and rule-based heuristics. Sameem built it as an engineer at Zencloud.
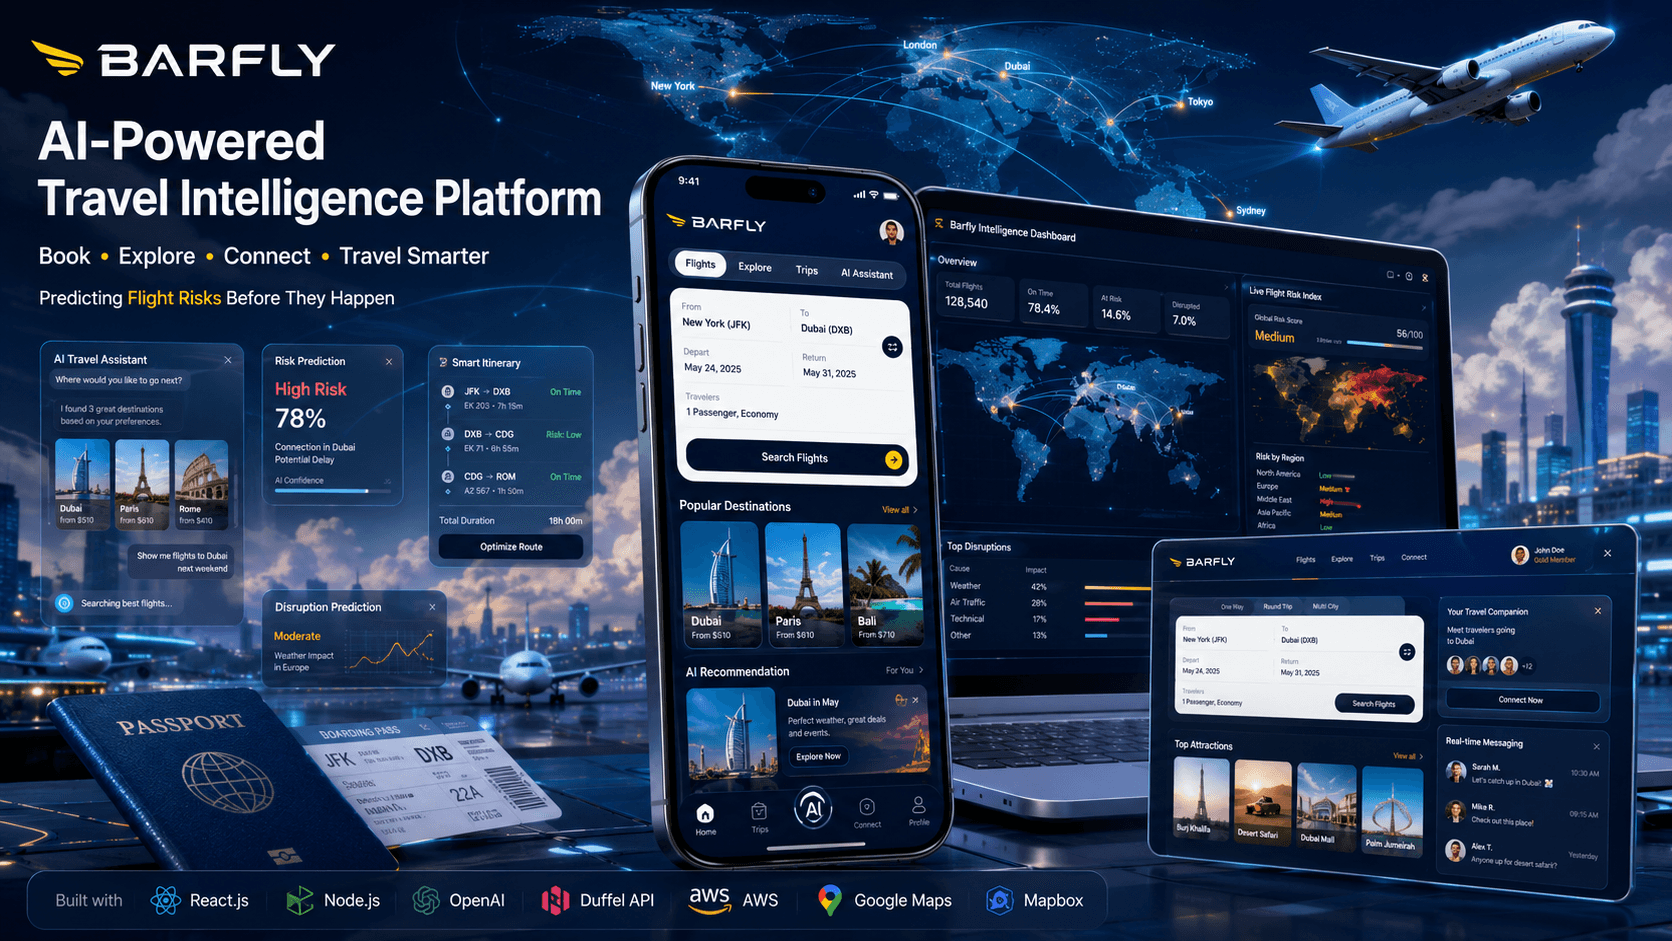
Facts about the build and who it was for. Any figure here is shown on a public store listing or site linked on this page — how we present portfolio work.
Project Story
Travel platforms struggled with a lack of real-time flight transfer risk assessments, resulting in a poor customer experience and unreliable booking processes.
As an engineer at Zencloud, Sameem built a Node.js risk module that combines Duffel API flight data with heuristic rules for airline protocols and connection times.
Live inside got2.travel.
Project Details
Barfly is a risk module for got2.travel that estimates how likely a flight connection is to go wrong. Sameem built it as an engineer at Zencloud: a Node.js engine that combines Duffel API flight data with heuristic rules for airline protocols and connection times, for both codeshare and non-codeshare itineraries.
Tech Stack
Where to See It
Category
Node.js Backend & AWSBarfly is a flight-transfer risk check: for a connecting itinerary, it assesses the risk that a delay breaks each layover. Sameem worked on it as an engineer at Zencloud. He designed the risk assessment module in Node.js, combining flight data from the Duffel API with heuristic rules built on airline protocols and real-world aviation variables, for both codeshare and non-codeshare itineraries. The check is live inside got2.travel, a trip-planning site, where it appears as a layover risk indicator with a risk level, a reason and a predicted delay.
What you can check
- Live in got2.travel: a layover risk indicator on flight itineraries (risk level, reason, predicted delay)
Each item points to something public: a store listing, a live site or a demo build. See our terms for how we present portfolio results.
What is the Barfly risk check, and where does it run?
A connecting itinerary is sold as one product but flown as two or more separately operated flights joined by a layover. The booking screen shows the connection time; it does not show whether that time is enough for that particular pair of flights. Barfly is a risk check that addresses that gap. It runs inside got2.travel, a trip-planning site, where flight itineraries carry a layover risk indicator for the outbound and return journeys, showing the layover time, a risk level, the reason for it, the flight type and a predicted delay.
Sameem worked on Barfly as an engineer at Zencloud. He designed the risk assessment module: it takes itinerary data from the Duffel API, applies heuristic rules that combine airline protocols with real-world aviation variables to predict disruption risk, and handles codeshare and non-codeshare itineraries as separate cases. The engine runs on Node.js. His work is the risk engine; got2.travel's other features, such as its layover planning and hotel search, are separate from it.
Why is a layover time not enough to judge a connection?
Price and connection time sit on the surface of every booking screen. Whether that connection time is sufficient for a given pair of flights is a different question, and a duration in minutes does not answer it. The same layover length does not carry the same exposure on every pairing: it depends on how reliable the inbound flight tends to be, what happens if it is late, and what the traveller has to do between the two flights.
So without help, the traveller is asked to price a risk they cannot see, and nothing in a published schedule distinguishes the safe cases from the fragile ones. A risk check adds the missing judgement to the itinerary: an assessment of each connection that a booking surface cannot produce by displaying schedule data alone.
What makes flight transfer risk hard to compute?
Connection risk is a conditional quantity rather than a property of any single flight. It depends on whether the inbound leg arrives late enough to break the outbound, so the calculation has to reason about two flights and the relationship between them at the same time.
The engine synthesises airline protocols and real-world aviation variables. Both halves matter. Aviation variables describe how a flight behaves; airline protocols describe what the carrier does about it, and those rules are carrier-specific. Two itineraries with identical published times can therefore warrant different assessments, which means the problem cannot be reduced to arithmetic on timestamps.
got2.travel shows the analysis being calculated when the check is requested, and computing on demand is a different engineering problem from computing offline. The inputs have to be gathered and combined when the question is asked rather than prepared in advance, and the cost of every lookup is paid inside the answer.
Why do codeshare and non-codeshare itineraries need separate handling?
The engine handles codeshare and non-codeshare itineraries as distinct cases. That distinction is a data modelling problem before it is a scoring problem.
A codeshare segment is sold under one carrier's flight number and operated by another. A non-codeshare segment is sold and operated by the same carrier. Because the engine applies airline protocols, and protocols belong to carriers, it has to resolve which carrier governs a segment before any rule can be applied to it. On a codeshare that mapping is not one to one, so marketing and operating identity have to be carried separately through the itinerary representation rather than collapsed into a single airline field.
A system that handled only the simple case would risk applying one carrier's rules to a flight another carrier actually operates, which is the kind of quiet error a risk check exists to prevent.
Why integrate the Duffel API rather than build carrier integrations?
A risk assessment is only as good as the itinerary data beneath it, and airline distribution is not a uniform data source. Content reaches consumer platforms through different channels and schemas, with different conventions for what a segment, a fare and an operating carrier are.
Duffel is the integration point. It offers programmatic flight search and booking across airline content behind a single interface, so a system built on it works against one normalised representation of an itinerary instead of reconciling per-carrier formats. For an engine whose distinguishing logic is the assessment itself, that normalisation is the enabling piece, because the structure the rules run over arrives as data.
It also removes undifferentiated work. Maintaining direct carrier connections is a permanent engineering cost that adds nothing to the risk assessment. Using a distribution layer concentrates the effort on the part of the product that is not a commodity.
Why heuristic rules rather than a trained model?
The engine pairs Duffel data with heuristic algorithms. That is a trade-off rather than a shortcut, and both sides of it are worth stating.
Heuristics encode domain rules directly. Airline protocols are stated rules, so a rule-based engine can express them without first accumulating a labelled history of outcomes. A heuristic system's behaviour follows from the rules it is given rather than from data it has been shown, which removes the dependence on a training corpus that a supervised model has by construction.
Rules are also legible. An assessment whose basis can be inspected is easier to act on and easier to tune, because it is possible to see which rule produced the output. The cost is a ceiling on subtlety and a standing maintenance burden, since every rule is written, reviewed and revised by hand rather than learned.
Why does the check give a reason as well as a risk level?
In got2.travel the indicator does not stop at a label. Alongside the risk level it shows the layover time, a reason, the flight type and a predicted delay. That output fits a rule-based engine well. A heuristic system can say which rule produced its answer, so the reason is a by-product of the design rather than an explanation reconstructed afterwards. A predicted delay set beside the layover time also gives a traveller something more usable than a label: a long layover with a modest predicted delay reads differently from a tight one at the same level.
The limits deserve the same plainness. A predicted delay is an estimate, and a risk level is best read as a way to compare two itineraries rather than a guarantee about either. Judging how good the predictions are needs a comparison against actual arrivals across many trips; a single itinerary cannot show it.
Where can you see the Barfly risk check?
The Barfly check is live inside got2.travel, a trip-planning site. Flight itineraries there carry a layover risk indicator for the outbound and return journeys, showing the layover time, a risk level, the reason for it, the flight type and a predicted delay. Sameem designed the risk assessment module behind that indicator as an engineer at Zencloud.
Why this stack
- Node.js is the runtime of the risk engine. A system defined by an outbound API integration plus rule evaluation is, as a class of workload, shaped by waiting on the network rather than by arithmetic, and a non-blocking event loop fits that class: concurrency is expressed as pending operations rather than as a thread held open per request, so many checks can be in flight at once. Running JavaScript on the server also keeps one language across a stack whose interface is React-based.
- React.js is the project's interface technology, and got2.travel's front end is built with Next.js, a React framework; Sameem's part is the engine behind the indicator. A component library suits this kind of output because a risk assessment is derived state: what is on screen is a view of data that changes when the itinerary changes. React expresses that as a rendering function of state rather than manual page edits, which keeps data and display from drifting apart as features accumulate.
- Duffel API: airline distribution is fragmented across channels and schemas, and a risk engine needs structured itineraries more than it needs any single carrier connection. Duffel provides programmatic flight search and booking behind one normalised interface, so an integrating system works against a consistent representation of segments, carriers and connection times instead of per-carrier parsing. That normalisation is what lets rules run over a stable structure, and it keeps the permanent cost of direct carrier integrations away from the part of the product that is distinctive.
- Heuristic algorithms: the engine synthesises airline protocols and aviation variables through heuristic rules. Encoding stated rules directly avoids the cold start a supervised approach carries, since a heuristic system's behaviour comes from the rules given to it rather than an accumulated history of outcomes. Rules also produce inspectable reasons, which matters when the output is advice a traveller acts on and an operator tunes. The trade-off is a ceiling on subtlety and ongoing hand maintenance of every rule.